
Introduction
AI writing tools have changed how people create articles, reports, emails, academic papers, and marketing content. Large language models (LLMs) can produce fluent text in seconds. However, their growing use raises an important question: can we determine whether a human or an AI system wrote a particular passage?
AI text fingerprinting explores this question through statistical analysis, natural language processing (NLP), and machine learning. These methods examine word choices, sentence structures, token probabilities, and other linguistic features. Some systems also analyze patterns that a particular language model tends to produce.
AI authorship attribution has practical applications in academic integrity, content moderation, fraud prevention, and digital forensics. However, no single linguistic feature can reliably establish authorship in every situation. Human writing can resemble AI output, and AI-generated text can closely resemble human writing after editing.
What Is AI Fingerprint Detection?
AI fingerprint detection uses machine learning to examine language patterns, compare linguistic features, and estimate whether a passage resembles machine-generated text.
AI text fingerprinting refers to techniques that analyze writing for patterns associated with particular language models or generation methods. These patterns may include predictable word sequences, recurring sentence structures, and statistical regularities in language.
Think of a fingerprint as a collection of clues rather than a unique identifier. A detector combines several signals to estimate whether a passage resembles AI-generated text.
For example, a system might examine whether a passage repeats similar sentence structures, uses predictable vocabulary, or follows unusually consistent linguistic patterns. However, a human writer can produce the same characteristics, especially when writing formal reports or technical documentation.
AI Text Fingerprinting vs. AI Authorship Attribution
These terms describe related but different tasks.
- AI text fingerprinting: Identifies statistical or stylistic patterns associated with generated text.
- AI authorship attribution: Estimates which author, model, or source produced a passage.
- AI text detection: Classifies text as likely human-written, AI-generated, or uncertain.
- Stylometric analysis: Examines measurable writing characteristics to compare authors or writing samples.
A detector that identifies likely AI-generated text does not automatically identify the exact model behind it. Reliable model attribution requires stronger evidence and appropriate reference samples.
How Machine Learning Language Pattern Detection Works
Most AI detection systems analyze text through several stages. The exact pipeline depends on the model, available data, and intended application.
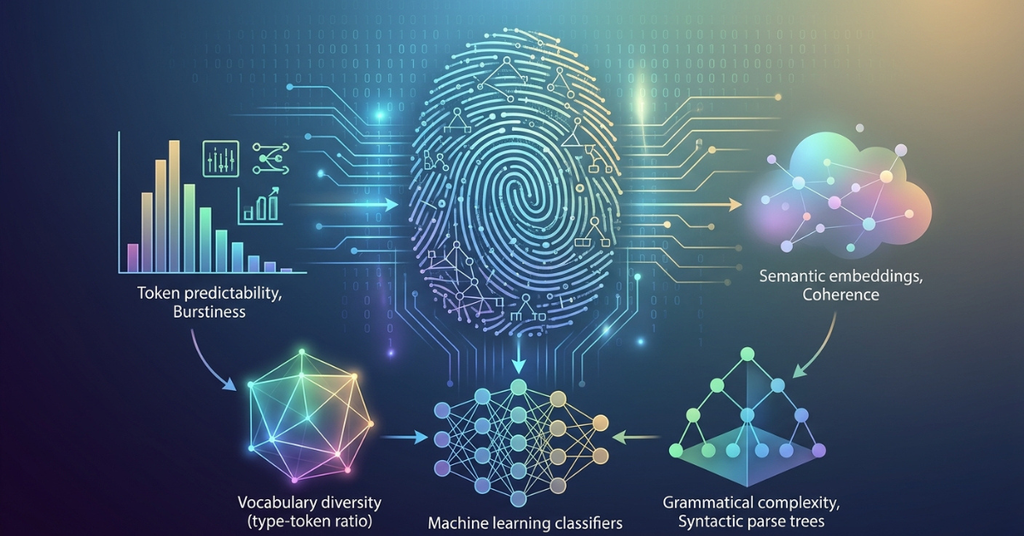
Machine learning models can combine lexical, syntactic, and semantic language patterns to identify statistical differences between human-written and AI-generated samples.

1. Text Preprocessing and Tokenization
First, the system prepares the text for analysis. It may normalize whitespace, segment sentences, identify punctuation, and tokenize the passage.
Tokenization divides text into units that a language model can process. These units may represent complete words, word fragments, punctuation marks, or other symbols.
There are four words in the phrase “Machine learning detects patterns.A particular tokenizer might divide one or more words into multiple tokens.
The detector then extracts features from these units. Depending on the method, it may examine token frequencies, sentence lengths, grammatical structures, or model-generated probability scores.
2. Statistical Feature Extraction
The system converts linguistic characteristics into numerical features. These features help a classifier compare the passage with examples from its training data.
Common features include:
- Word and phrase frequencies.
- Vocabulary diversity.
- Sentence-length variation.
- Part-of-speech distributions.
- Grammatical structure.
- Token probability distributions.
- Semantic embeddings.
- Perplexity scores.
A classifier may combine these features to estimate whether a passage resembles its human-written or machine-generated examples.
However, the system’s output reflects patterns in its training data. It does not provide direct access to the writer’s identity or intentions.
3. Classification and Confidence Assessment
After feature extraction, a classifier produces a score or category. Some systems return a probability-like value, while others provide labels such as “likely AI-generated” or “likely human-written.”
Users must interpret these outputs carefully. A score of 90% does not necessarily mean that the text has a 90% chance of being AI-generated. That interpretation depends on the system’s calibration, validation data, and scoring method.
Developers should document what each score means and test how often the system makes incorrect predictions.
Key Methods for Detecting LLM Writing Styles
Researchers use several methods to investigate machine-generated language. Each method captures different evidence and has distinct limitations.
Perplexity and Burstiness in AI Text
The complexity of a sequence of tokens under a particular language model is determined by its predictability. Lower perplexity generally means the model assigns higher probabilities to the observed token sequence.
Some researchers use perplexity to investigate AI-generated text because language models often produce sequences that fit their learned probability distributions.
However, low perplexity does not prove AI authorship. Formal writing, common expressions, simple vocabulary, and second-language writing can also produce predictable text.
Burstiness describes variation in a feature across a passage. In AI detection discussions, it often refers to variation in sentence lengths or other linguistic characteristics.
Consider these examples:
- Example A: “The system collects data. It checks the results. It generates a report.”
- Example B: Data is collected, checked, and a report is generated before an analyst receives the results.”
Example A uses three short sentences. Example B uses a longer sentence with several connected actions.
Neither example proves human or AI authorship. A person may prefer short sentences, and an LLM can generate varied sentence structures.
Researchers should therefore measure perplexity and burstiness alongside other features instead of treating either metric as a definitive detector.
N-Gram Frequency Analysis
An n-gram represents a sequence of n consecutive tokens or words. A unigram contains one unit, a bigram contains two, and a trigram contains three.
A detector might analyze common phrases such as “in conclusion,” “it is important to,” or “as a result.” It can compare their frequencies across human-written and AI-generated samples.
Repeated phrase patterns may help a classifier identify a particular dataset or writing style. However, common phrases appear in many forms of writing.
N-gram analysis works best as one feature within a broader system. It becomes less dependable when writers edit generated text, change topics, or use phrases that the detector rarely encountered during training.
Token Probability Distributions
Language models assign probabilities to possible next tokens. These probabilities help the model select or generate text.
A researcher with suitable model access can examine the probabilities that a model assigns to a passage. Researchers can also compare probability distributions across different models.
It is important to keep in mind, however, that ordinary published texts do not reveal their original token probabilities.A third-party detector cannot recover a source model’s complete generation history simply by reading the final passage.
Access to model probabilities, the original model, or relevant generation records can make this analysis more informative.
Transformer Output Signatures
Transformers use attention mechanisms and other neural network operations to process sequences. Their internal activations and probability distributions can reveal information about model behavior.
Researchers may investigate these signals when they have access to the relevant model or generation environment. Yet the final text alone does not expose every internal computation.
A useful distinction matters here: researchers can analyze observable output patterns without claiming that every model leaves a unique, recoverable signature in ordinary text.
Stylometric Analysis for Machine-Generated Content
Stylometry measures writing characteristics such as vocabulary, punctuation, sentence length, and grammatical preferences.
For AI authorship attribution, researchers can compare these characteristics across reference samples. A system might examine whether two passages share unusual phrase patterns or similar distributions of sentence structures.
A basic measure of vocabulary diversity is the Type-Token Ratio (TTR).It divides the number of unique word types by the total number of word tokens.
In this example, the TTR is 0.80 for a passage that contains 80 unique words out of 100 total words.
However, TTR changes with document length. Researchers should consider length-adjusted alternatives, such as moving-average TTR, when they compare passages of different sizes.
Stylometric features can support attribution, but they rarely establish authorship on their own.
Linguistic Markers of Artificial Intelligence
Researchers often examine several linguistic signals together. The following table summarizes common features and their limitations.
| Feature | What it measures | Main limitation |
| Perplexity | Token predictability under a model | Human writing can also have low perplexity |
| Burstiness | Variation in sentence or feature lengths | Writers naturally use different levels of variation |
| N-gram frequency | Repeated word sequences | Common phrases appear in human and AI writing |
| Type-Token Ratio | Vocabulary diversity | Document length affects the result |
| Parse tree depth | Grammatical complexity | Topic and writing style influence syntax |
| Semantic embeddings | Meaning and contextual similarity | Similar meaning does not establish common authorship |
| Stylistic entropy | Variation or uncertainty in selected features | Results depend on the chosen measurement |
| Classifier scores | Similarity to learned classes | Training data and calibration affect reliability |
Syntactic Parse Tree Anomalies
A syntactic parser represents a sentence’s grammatical structure as a tree. Researchers can examine tree depth, clause counts, phrase structures, and sentence complexity.
Some generated passages may show repeated grammatical patterns. A classifier can learn whether these patterns help distinguish its training examples.
However, a consistent syntax does not automatically indicate AI authorship. Legal documents, scientific papers, and technical manuals often follow strict grammatical conventions.
Semantic Coherence and Stylistic Entropy
Semantic embeddings represent text as numerical vectors. Researchers can compare these vectors to study meaning, topic shifts, and similarities between passages.
For example, a system might compare adjacent paragraphs to identify abrupt changes in topic or meaning.These changes may point to editing issues, but they do not prove that AI wrote the text.
Stylistic entropy measures variation or uncertainty within selected writing features. Researchers must define the feature and calculation clearly because the term does not refer to one universal AI detection metric.
Together, semantic and stylistic features can help describe a passage more thoroughly than a single score.
The False Positive Crisis: Evaluating 50,000 Academic and Professional Submissions Across 4 Commercial Detectors
A credible benchmark should measure both detection accuracy and the harm that incorrect classifications can cause. The proposed 50,000-submission evaluation offers a useful research design, but it requires an actual dataset and documented experiments before researchers can report results.
Why False Positives Matter
A false positive occurs when a detector labels human-written text as AI-generated. This error can harm students, researchers, job applicants, and professionals who rely on their writing to demonstrate their knowledge.
A 2023 study by Liang and colleagues examined seven GPT detectors using English writing samples from native and non-native speakers. The researchers reported an average false-positive rate of 61.3% for 91 TOEFL essays written by non-native English speakers. The study also found that simple prompting changes could help generated text evade detection. These results highlight serious risks, although they do not establish the performance of every current detector.
How to Design a 50,000-Document Benchmark
Researchers should collect a balanced dataset of human-written and AI-generated documents. They should include academic essays, professional reports, technical articles, and other relevant text types.
The dataset should also represent different English proficiency levels, subject areas, document lengths, and writing conditions.
Researchers should compare four detector configurations or products with clearly documented versions. They should record the model, test date, language settings, and any preprocessing requirements.
The benchmark should include these measurements:
| Metric | Definition | Why it matters |
| False-positive rate | Human samples incorrectly flagged as AI | Measures risk to genuine writers |
| False-negative rate | AI samples incorrectly classified as human | Measures missed generated text |
| Precision | Correct AI predictions divided by all AI predictions | Shows how often positive flags are correct |
| Recall | Correctly identified AI samples divided by all AI samples | Shows how many generated samples the system catches |
| F1 score | Harmonic mean of precision and recall | Summarizes performance across both measures |
| AUROC | Area under the receiver operating characteristic curve | Measures ranking performance across thresholds |
Researchers should report actual measurements only after they run the experiment. They should also calculate confidence intervals and compare results across relevant subgroups.
Why Uniform Syntax Can Trigger False Positives
Some detectors rely heavily on predictable vocabulary, limited linguistic variation, or recurring sentence structures. These features can appear in both generated text and genuine human writing.
A student who uses simple grammar may produce predictable sentences. A technical writer may repeat the same terminology throughout a report. A professional may follow a strict template.
A detector that treats these patterns as strong evidence of AI authorship may unfairly flag such writing.
Researchers should therefore evaluate false-positive rates separately for different language backgrounds, document types, and writing styles. They should also test edited AI text rather than relying exclusively on untouched model outputs.
The Multi-Tier Stylometric Audit Framework: Moving Beyond Simple Perplexity
A practical detection framework should combine multiple features, document uncertainty, and test its decisions against reliable reference data.

The following three-tier framework offers a structured approach for engineers and content strategists.
Tier 1: Lexical Analysis
The lexical layer examines words, phrases, and vocabulary variation.
Researchers can measure:
- Type-Token Ratio and related vocabulary metrics.
- N-gram frequency distributions.
- Repeated phrases and unusual word combinations.
- Perplexity scores, when researchers have suitable model access.
- Sentence-length distributions and burstiness.
The system should account for document length and subject matter. Otherwise, it may confuse ordinary writing conventions with signs of generated text.
Tier 2: Syntactic Analysis
The syntactic layer examines how writers organize words and clauses.
Researchers can measure sentence length, clause count, parse tree depth, part-of-speech distributions, and grammatical structure.
The system can then compare these features with reference samples. However, it should not assume that one grammatical style belongs exclusively to humans or AI systems.
Tier 3: Semantic Analysis
The semantic layer examines meaning and relationships across sentences or paragraphs.
Researchers can use embeddings to compare semantic similarity, identify abrupt topic shifts, and examine how consistently a passage develops its main ideas.
These measurements can reveal unusual patterns, but semantic consistency does not prove human authorship. Both people and LLMs can produce coherent or inconsistent text.
Text-to-Feature Mapping Workflow
A useful architecture follows this sequence:
Raw text → preprocessing → tokenization → lexical, syntactic, and semantic features → feature normalization → classifier → calibrated score → human review.
The preprocessing stage prepares the document. The feature extraction stage measures its linguistic properties. The classifier combines those measurements, while calibration helps align scores with observed outcomes.
The final review stage considers context, source records, and the consequences of a wrong decision.
Developers should also preserve version information and log the features and model configuration that produced each result. This process supports debugging, auditing, and future evaluation.
Case Study: Tracing Stylistic Drift and Evasion Patterns in Large-Scale Content Pipelines
The following scenario illustrates a possible enterprise investigation. It does not describe a verified company deployment or report measured business results.
The Initial Detection Failure
Imagine a content platform that uses a perplexity threshold to flag potentially generated submissions. The detector performs reasonably well on the original samples in its test set.
Over time, some submissions begin to escape the filter. Their authors use prompts that request different sentence lengths, varied vocabulary, and a more conversational tone. Some users also edit the output before submitting it.
These changes alter the linguistic features that the original detector relies on. The system may miss some generated text while continuing to flag genuine human writing with similar characteristics.
This example illustrates why developers should test detectors against varied generation methods and editing conditions.
The Proposed Machine Learning Patch
The engineering team could replace a single hard threshold with a multi-feature classifier. The new system would combine lexical statistics, syntactic measurements, semantic embeddings, and contextual information.
Semantic embedding clustering could help the team identify groups of submissions with similar content or linguistic representations. However, clusters alone cannot prove that the same model or author produced the documents.
The team should evaluate the new system on a separate test set. It should also compare results against the original detector under the same conditions.
How to Measure Business Outcomes
The team should track several operational measures:
- False-positive and false-negative rates.
- Precision and recall across relevant user groups.
- Review workload and average review time.
- Detection performance on edited or paraphrased samples.
- Model latency and computational cost.
- Performance changes as writing styles and generation tools evolve.
The team should report the actual results after testing. Without measured data, it cannot responsibly claim a specific improvement in accuracy, reduced costs, or faster review.
Adversarial Evasion and the Limits of AI Detection
Adversarial evasion occurs when changes to input text or generation methods cause a detection system to perform less reliably.
Writers can edit generated text, paraphrase sentences, combine human and AI writing, or change the prompt used to generate a passage. These changes may weaken the features that a detector learned during training.
Researchers should test detection systems against these conditions before deploying them in high-impact settings.
How Developers Can Improve Robustness
Developers should train and evaluate systems using diverse samples. They should include multiple models, topics, writing styles, and editing conditions.
They should also separate training and test data carefully. If near-duplicate documents appear in both sets, the evaluation may overstate real-world performance.
Finally, teams should monitor stylistic drift. As models and writing practices change, the relationship between linguistic features and authorship can weaken. Regular evaluation helps teams detect these changes before they cause widespread errors.
Semantic Watermarking and Other Verification Methods
The purpose of semantic watermarking and statistical text watermarking is to provide evidence of generated content.Some watermarking methods influence token selection during generation so that a detector can later test for a statistical signal.
These methods differ from ordinary text classification. A classifier infers likely authorship from learned patterns, while a watermark detector searches for a signal that a generation process deliberately introduced.
Watermarks also have limitations.It may weaken the signal if text is edited, translated, paraphrased, or transformed in any way. A watermarking system also needs appropriate support from the generation process.
For stronger verification, organizations can combine detection with provenance records, authenticated generation logs, document version histories, and clear disclosure policies.
No single method answers every authorship question. The best approach depends on the available evidence and the consequences of an incorrect decision.
How to Build a Perplexity and Burstiness Visualizer
A visualizer can help readers understand why detection systems examine more than individual words.
A useful interactive tool could let users paste a paragraph and display sentence lengths, variation across sentences, and selected model-based predictability scores.
The tool should explain that sentence length is only a simple proxy for stylistic variation. It should not label a passage as human-written merely because its sentences vary in length.
A more advanced version could display token-level scores when users supply a compatible language model. It could also show how editing changes the measurements.
The interface should include three safeguards:
- Explain each metric in plain language.
- Distinguish direct measurements from model predictions.
- Warn users that the visualization cannot establish authorship.
For privacy, developers should disclose whether the tool uploads text to a server, retains submissions, or shares data with external services.
Anatomy of an AI Authorship Classifier
An architecture diagram can make the detection pipeline easier to understand.
The diagram should begin with raw text and move through preprocessing, tokenization, feature extraction, classification, and final review.

The feature extraction stage should branch into three groups:
- There are three major lexical features: n-grams, vocabulary diversity, and token probabilities.
- Syntactic features: sentence length, clause structure, and parse tree measurements.
- Semantic features: embedding similarity, topic consistency, and contextual relationships.
The branches should then connect to a classification model. The output should show a score or category, followed by a review step that considers uncertainty and supporting evidence.
This design helps readers understand that the classifier combines several signals rather than discovering a single universal AI fingerprint.
An accompanying five-minute explainer video could demonstrate the pipeline with sample text. A researcher or linguist could explain probability distributions, sentence variation, and the difference between statistical clues and proof of authorship.
Best Practices for Responsible AI Authorship Attribution
Organizations should establish clear rules before using detection tools to make important decisions.
First, they should treat detector results as evidence for further investigation, not automatic proof of misconduct. Second, they should validate tools on the same types of documents and users they intend to assess.
Third, they should allow affected writers to provide drafts, notes, version histories, or other relevant evidence. These records can help reviewers understand how a document developed.
Finally, organizations should document their thresholds, error rates, and review procedures. They should update their systems when new evidence reveals weaknesses.
A responsible process protects genuine writers while helping organizations investigate suspicious activity more consistently.
Frequently Asked Questions
1. What is AI text fingerprinting?
AI text fingerprinting analyzes statistical and linguistic patterns that may indicate machine-generated text. It can examine vocabulary, sentence structures, token probabilities, and other features. However, it cannot reliably identify every AI-generated passage or prove authorship on its own.
2. Can machine learning detect AI-generated text accurately?
Machine learning can distinguish human-written and AI-generated samples under certain conditions. Accuracy depends on the training data, model, document type, and evaluation method. Editing and new generation techniques can reduce performance.
3. What are perplexity and burstiness in AI text?
Perplexity measures how predictable text appears under a language model. Burstiness describes variation in a selected feature, such as sentence length. Researchers can use both measurements to study writing patterns, but neither proves AI authorship.
4. Why do AI detectors flag human writing?
Detectors may confuse predictable vocabulary, repeated grammatical structures, or limited linguistic variation with patterns in their AI training samples. Research has documented false positives involving non-native English writing. Reviewers should consider these risks before making decisions.
5. Can writers bypass AI text detection?
Editing, paraphrasing, and different generation methods can change the features that detectors rely on. Researchers have documented weaknesses in existing approaches. However, no single editing method guarantees that a detector will miss generated text.
6. What is the difference between AI detection and authorship attribution?
AI detection estimates whether text resembles machine-generated content. Authorship attribution attempts to connect text to a particular author, model, or source. Attribution generally requires suitable reference samples or additional provenance evidence.
7. Does semantic watermarking prove AI authorship?
A verified watermark can provide evidence that text passed through a compatible generation process. However, watermark reliability depends on the method, implementation, and subsequent text transformations. Reviewers should consider the watermark alongside other evidence.
8. Should schools and businesses rely on AI detectors alone?
No. Schools and businesses should combine detector results with document history, direct evidence, transparent policies, and human review. They should also test false-positive rates and give people a fair opportunity to explain their work.
Conclusion
AI fingerprint detection uses machine learning to analyze language patterns and investigate characteristics associated with machine-generated text. Perplexity, burstiness, stylometry, token probabilities, and semantic embeddings can all contribute useful evidence. However, none provides a universal test of authorship. Developers should evaluate false positives, test adversarial changes, and monitor performance across different writing groups. Organizations should treat detector scores as clues, verify claims with additional evidence, and use human review before making consequential decisions.

I am Qasim Ali, a technology enthusiast passionate about exploring the latest innovations shaping our digital world. With 5+ years of experience in technology and digital trends, I share practical insights on AI, software, hardware, cybersecurity, programming, and emerging technologies. Through Techvens, my goal is to simplify complex technology and help readers stay informed, confident, and ahead in the fast-moving tech world.